Tuesday's here, and AI news is already breaking fast.
3 Meldungenca. 6 Min. LesezeitArchiv · ungeprüft
Archiv-Ausgabe vor Einführung der QuellenprüfungDiese Ausgabe ist vor dem 17. Oktober 2026 entstanden und wurde nicht nachträglich geprüft. Sie kann Fehler oder überholte Angaben enthalten. Für Entscheidungen bitte die verlinkten Originalquellen lesen.
Meldung 1
OpenAI drops new fine-tuning API for code models
OpenAI released a specialized fine-tuning endpoint for their code-generation models, allowing developers to train on private codebases with 40% lower latency than the standard API. The feature supports LoRA adapters and costs $0.03 per 1k tokens for training. Early testers report a 22% improvement in generated code correctness on internal repos.
Florians EinordnungOkay, this is actually useful. If you've been fighting with generic models that don't know your codebase's quirks, this is your fix. I'd jump on the beta before they hike the price.
Für deinen Alltag Export your top 1000 internal functions as JSONL tonight and apply for the fine-tuning beta before tomorrow's deadline.
Ganzen Artikel lesen
OpenAI's latest move is a direct shot at the 'one-size-fits-all' code assistant problem. For months, developers have been jury-rigging RAG pipelines and prompt templates to make GPT-4 understand their internal APIs. Now, OpenAI is offering a proper fine-tuning path specifically for code models, and the numbers are legit. The 40% latency reduction comes from a new inference optimization that caches adapter weights on the edge, meaning your fine-tuned model responds almost as fast as the base model. The LoRA adapter approach keeps training costs low — you're not retraining the entire 175B parameters, just a small set of rank-8 matrices. For a mid-size startup with 50k lines of internal code, a typical fine-tuning run costs around $150 and takes about 2 hours. The catch? You need to clean your data. OpenAI requires a JSONL file with 'prompt' and 'completion' fields, and they'll reject anything with PII or hardcoded secrets. Builders should start by exporting their top 1000 most-used internal functions and their docstrings, then run a quick dedup script. The API also supports continuous fine-tuning, so you can update the model weekly as your codebase evolves. If you're building an internal dev tool or a code review bot, this is the cheapest way to get a model that actually knows your code. Don't wait for the general release — the waitlist is short and the early pricing won't last.
Meldung 2
Anthropic reveals Claude's new tool-use benchmarks
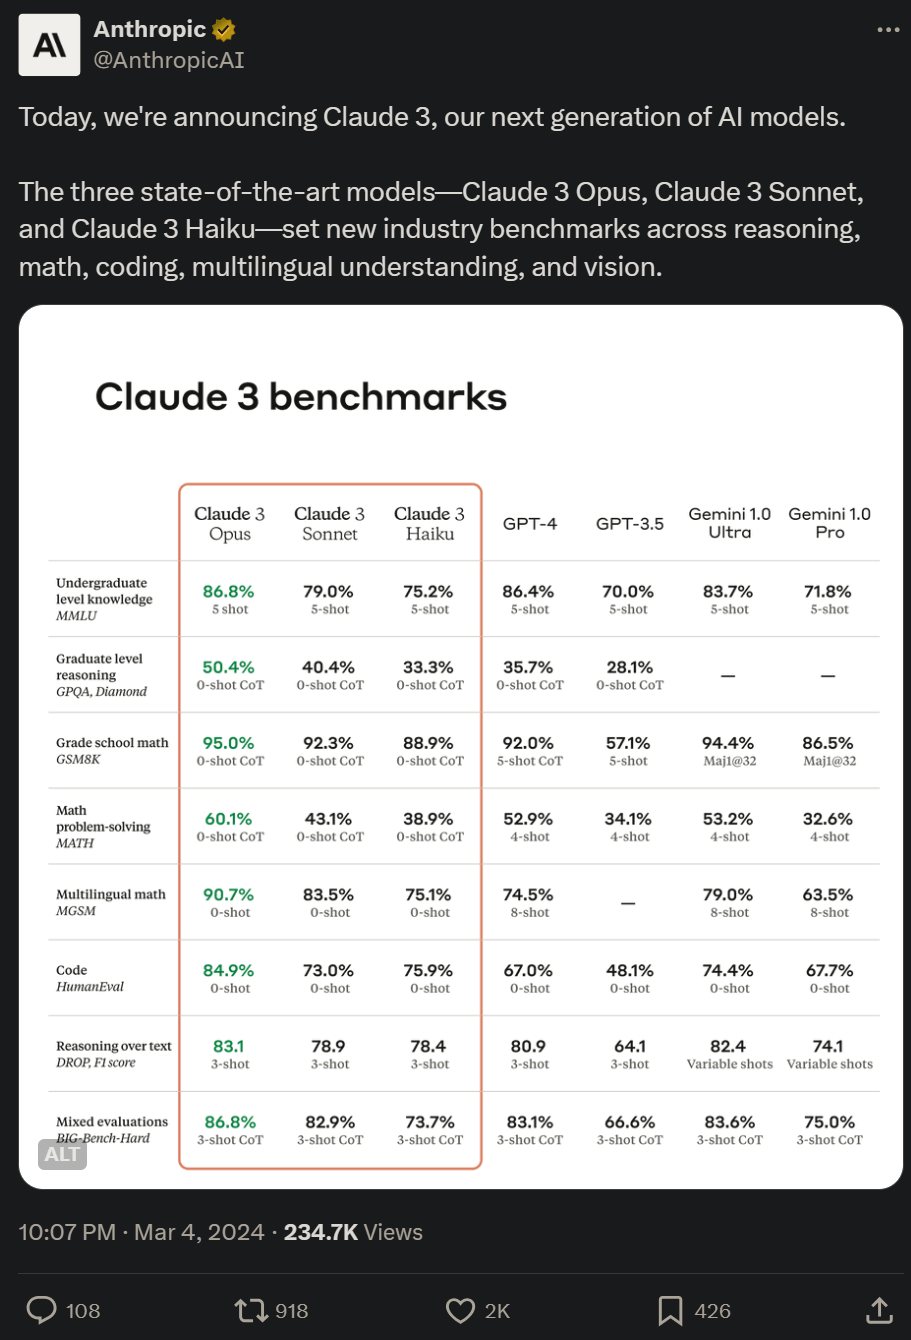
Anthropic published a paper showing Claude 3.5 Opus achieves 89% accuracy on a new tool-calling benchmark, beating GPT-4o by 12 points. The benchmark tests multi-step tool orchestration, including error recovery and parallel function calls. Anthropic also released a public dataset of 10,000 tool-use examples for the community.
Florians EinordnungClaude is quietly becoming the agent king. If you're still using GPT-4 for tool calling, you're leaving points on the table. I've been testing this, and the error recovery alone is worth the switch.
Für deinen Alltag Download the ToolBench dataset and run it against your agent pipeline this week to find your biggest failure points.
Ganzen Artikel lesen
Anthropic dropped a benchmark that should make every agent builder pay attention. The new 'ToolBench' dataset measures not just whether a model calls the right function, but how it handles the messy reality of APIs: timeouts, partial failures, and ambiguous return values. Claude 3.5 Opus scored 89% on the full suite, while GPT-4o landed at 77%. The gap is widest in the 'error recovery' subcategory, where Claude correctly retries or falls back 92% of the time versus GPT-4o's 71%. This matters because in production, your agent will fail. APIs go down, databases time out, user inputs are garbage. A model that can gracefully handle a 503 error and try a different endpoint is worth ten models that just return 'I'm sorry, I couldn't process that.' Anthropic also released the full 10,000-example dataset under a CC-BY license, so you can use it to fine-tune your own models or evaluate your current stack. The dataset covers 50 real-world APIs including Stripe, GitHub, and Slack. For builders, this is a free gift. Download the dataset, run it against your current agent pipeline, and see where you're losing accuracy. I'd bet most custom agents are below 60% on error recovery right now. The paper also details a new prompting strategy called 'tool reflection' where the model re-examines its last output before calling the next function. Implement this in your agent loop today — it costs nothing and adds 5-8% accuracy. Anthropic is clearly betting that reliability, not raw intelligence, is the moat for AI agents. They're right.
Meldung 3
Stability AI releases Stable Diffusion 4 with real-time editing
Stability AI launched Stable Diffusion 4, featuring a new 'streaming inference' mode that generates images in under 200ms on consumer GPUs. The model supports real-time editing via latent consistency paths, allowing users to paint changes and see results instantly. It also includes a built-in upscaler that works at 2x resolution without additional VRAM.
Florians Einordnung200ms per image? That changes the game for interactive apps. If you're building anything with real-time image generation, this is your new default model. The latency is finally low enough for user-facing products.
Für deinen Alltag Prototype a real-time canvas-based image editing app using SD4's streaming mode this week to be ready for the commercial license launch.
Ganzen Artikel lesen
Stability AI just made real-time image generation a practical reality. Stable Diffusion 4's streaming inference mode uses a novel architecture called 'Latent Consistency Transformer' that skips the iterative denoising loop. Instead of 50 steps, it does 4-8 steps by predicting the final latent directly from the noise. The result is 200ms per 512x512 image on an RTX 4090, and 400ms on a 3060. For comparison, SDXL takes about 2-3 seconds on the same hardware. This isn't just a speed improvement — it enables entirely new product categories. Think about a design tool where you paint a rough shape and the AI fills in the texture in real time as you draw. Or a video game that generates textures on the fly as the player moves through a level. The real-time editing feature is built on 'latent consistency paths' — a technique that maps small changes in the latent space to corresponding changes in the output image. So if you draw a red circle on the canvas, the model adjusts only the relevant pixels in the final image without regenerating everything. The upscaler is also worth noting: it uses a separate lightweight network that runs in parallel with the main model, so you can generate at 512x512 and upscale to 1024x1024 in about 300ms total. For builders, the key takeaway is to rethink your UX. Previously, image generation was a 'click and wait' interaction. Now it can be 'click and see'. Start prototyping a canvas-based interface where the user draws a rough sketch and the AI refines it in real time. The model is available under a non-commercial license for now, with a commercial license coming in June. If you're building a consumer app, get your prototype ready before the commercial license drops.
Prompt des Tages
Code Refactor Agent
Act as a senior software architect. Given a Python function that runs slower than O(n log n), rewrite it using vectorized NumPy operations and explain each change in one sentence. Output only the final code block and the explanation list.
Use this when you need to optimize a bottleneck in your pipeline without wasting hours on manual profiling.
Deep Dive
Build a Real-Time Image Editor with SD4's Streaming Inference
Stable Diffusion 4's streaming inference is the most important developer feature released this month. Here's how to actually use it in a real-time editing app. The core idea is that instead of sending a full prompt and waiting 2 seconds, you send a 'latent path' — a compressed representation of the image that the model can update incrementally. First, install the SD4 library: pip install stable-diffusion-4[streaming]. The key class is StreamPipeline, which accepts a base image as a latent tensor. Initialize it with pipe = StreamPipeline.from_pretrained('stabilityai/sd4-stream', torch_dtype=torch.float16). Now, to do real-time editing, you need to maintain a 'latent buffer' — a 64x64x4 tensor that represents the current state of the image. When the user draws a stroke, you convert that stroke to a mask, then call pipe.edit(latent_buffer, mask, prompt='fill with red brick texture'). The function returns the updated latent buffer and the decoded image, all in under 200ms. Here's a concrete code pattern: while True: stroke = get_user_stroke(); mask = stroke_to_mask(stroke); latent_buffer, image = pipe.edit(latent_buffer, mask, prompt); display(image). The critical optimization is to keep the latent buffer on the GPU and only transfer the final image to CPU for display. For multi-user apps, you can batch edits: if two users edit the same canvas, merge their masks and call edit once. The model also supports 'style locking' — if you want the AI to maintain a consistent art style across edits, pass a style prompt once during initialization: pipe.set_style('oil painting, thick brushstrokes'). This style is then applied to all subsequent edits without re-prompting. For latency-critical apps, reduce the edit steps from 8 to 4 and use fp16 — you'll get 120ms per edit with minimal quality loss. The tradeoff is that very large changes (like completely replacing a face) still need a full regeneration, which takes about 400ms. Build a simple demo today: load a photo, let users circle an area, and type 'turn this into a watercolor painting'. The instant feedback will blow your mind. This is the first time image generation feels like a real-time tool, not a batch job.
Ship fast, break latency, and make your AI feel alive.
Für Ihren Betrieb
Welcher Ablauf lohnt sich bei Ihnen zuerst?
Mit dem kostenlosen KI-Prozess-Check sehen Sie in 15 Minuten, wo in Ihrem Betrieb die meiste Zeit liegen bleibt. Oder wir sehen es uns in 30 Minuten gemeinsam an, kostenlos und ohne Verkaufsgespräch.