Archiv-Ausgabe vor Einführung der QuellenprüfungDiese Ausgabe ist vor dem 17. Oktober 2026 entstanden und wurde nicht nachträglich geprüft. Sie kann Fehler oder überholte Angaben enthalten. Für Entscheidungen bitte die verlinkten Originalquellen lesen.
In einer Minute im Bild
Google launched Gemma 4 12B, a multimodal model that fits in 16GB VRAM, making local AI on Mac and mobile a real option.
Meta replaced open Llama with proprietary Muse Spark for all 1.2 billion users, closing off free weights and signaling a major shift away from open-source AI.
OpenAI retired GPT-4.5 and o3 while upgrading GPT-5.5 Instant, and Anthropic filed for IPO at a $965 billion valuation—the AI industry is consolidating and maturing fast.
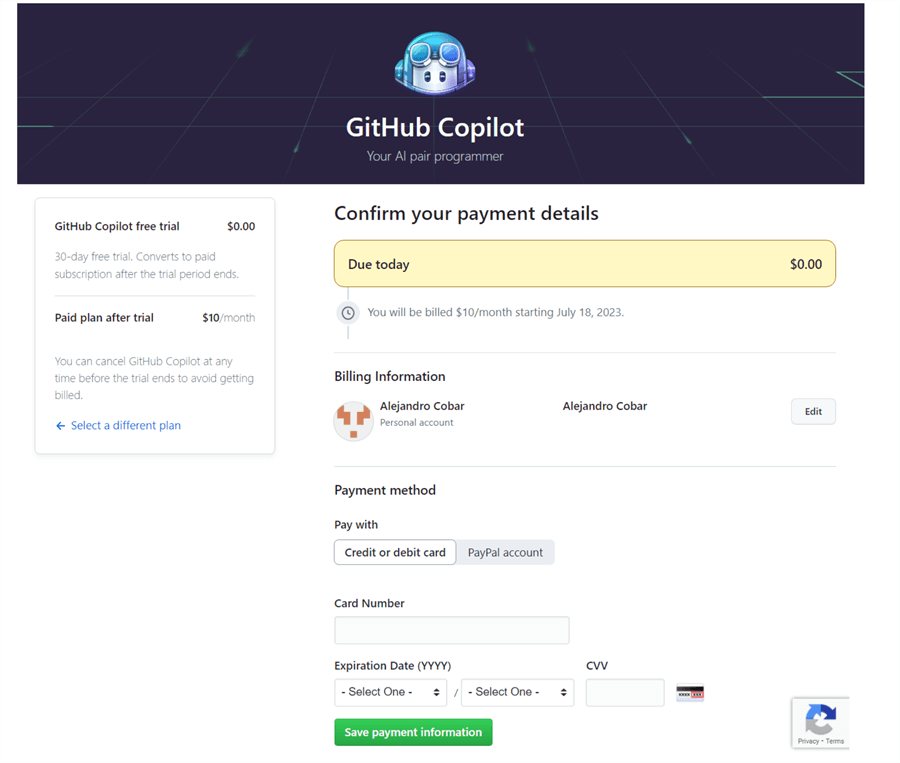
GitHub Copilot moved to usage-based billing with AI Credits, forcing developers to rethink how they use AI coding assistants.
Meldung 1
Google Gemma 4 12B Runs AI Locally on 16GB VRAM
Google released Gemma 4 12B on June 3, a dense multimodal model that removes vision and audio encoders, projecting raw audio into text token space and using a lightweight embedding module for vision. It matches the performance of Google's larger 26B MoE model while requiring half the memory, fitting in 16GB VRAM for on-device workflows on macOS and mobile.
Florians EinordnungThis is the first model that makes local multimodal AI actually practical for consumer hardware. If you've been waiting to run AI without cloud costs or privacy leaks, this is your green light.
Für deinen Alltag Download Gemma 4 12B and test it on your local machine this week to see if it replaces your cloud AI calls.
Ganzen Artikel lesen
Google's release of Gemma 4 12B on June 3 marks a pivotal moment for local AI. Unlike earlier models that required massive server farms, this dense model removes both vision and audio encoders—a radical architectural choice. By projecting raw audio directly into text token space and using a lightweight embedding module for vision, it cuts memory requirements in half while maintaining benchmark performance close to the 26B MoE variant. For developers, this means you can run a capable multimodal model on a standard MacBook Pro with 16GB of unified memory or on high-end mobile devices. The implications are immediate: privacy-sensitive applications like medical imaging analysis, real-time transcription without cloud uploads, and offline coding assistants become viable. Google also launched AI Edge Gallery and Eloquent apps for macOS to showcase these capabilities, including local coding and voice dictation. If you've been hesitant to build on-device AI because of hardware constraints, the barrier just dropped significantly. The next step is to test Gemma 4 12B against your specific use case—try running it on a laptop before committing to cloud infrastructure.
Meldung 2
Meta Closes Llama Weights, Goes Proprietary with Muse Spark
Meta replaced the open Llama model with its proprietary Muse Spark model for all 1.2 billion monthly Meta AI users, effectively closing the weights that were previously distributed for free. The company also launched a new AI agent for businesses on WhatsApp and Messenger to automate customer interactions and sales.
Florians EinordnungMeta just killed the open-source AI dream for its flagship product. If you built on Llama expecting long-term free access, you now have a migration problem.
Für deinen Alltag Audit your Llama-based projects today and identify a migration path to Gemma 4 or another open model before Meta fully shuts off access.
Ganzen Artikel lesen
Meta's decision to replace Llama with the proprietary Muse Spark model for all 1.2 billion monthly Meta AI users is a seismic shift in the AI landscape. For years, Meta positioned itself as the champion of open-source AI, releasing Llama weights freely and building a massive developer ecosystem. That era ended on June 4, 2026. The Muse Spark model is closed-weight, meaning developers who built applications on Llama can no longer access the underlying model for fine-tuning or local deployment. Meta is also launching a new AI agent for businesses on WhatsApp and Messenger, which will run on Muse Spark exclusively. This move mirrors a broader trend: as AI models become more capable and expensive to train, companies are locking down their IP. For the open-source community, this is a gut punch. Llama-powered projects now face an uncertain future—either migrate to alternatives like Gemma 4 or accept dependency on Meta's API. The strategic rationale is clear: Meta wants to monetize AI through its platforms, not give away the crown jewels. Developers should immediately audit their Llama dependencies and evaluate alternatives like Gemma 4 or DeepSeek's open models. The window for free, open-source frontier models is closing.
Meldung 3
GitHub Copilot Switches to Usage-Based Billing
Effective June 1, 2026, GitHub Copilot moved to consumption-based pricing using AI Credits, with code review now consuming GitHub Actions minutes. New sign-ups for Copilot Pro, Pro+, and Student plans are paused, usage limits tightened for individual plans, and Opus models are no longer available in Pro plans.
Florians EinordnungIf you're a heavy Copilot user, your costs just became unpredictable. This is a signal that AI coding assistants are entering a metered era—plan accordingly.
Für deinen Alltag Calculate your monthly Copilot usage and compare it to the new AI Credits pricing—if it's higher than $20, explore local alternatives like Gemma 4 or Mistral Vibe.
Ganzen Artikel lesen
GitHub's transition to usage-based billing for Copilot, effective June 1, 2026, represents a fundamental shift in how developers pay for AI coding assistance. Under the new system, every interaction consumes AI Credits: code completions, chat queries, and code reviews all draw from a shared pool. Code review now also consumes GitHub Actions minutes, adding another metered dimension. New sign-ups for Copilot Pro, Pro+, and Student plans are paused, suggesting GitHub is consolidating its offerings. Usage limits are now displayed within VS Code and the Copilot CLI to help developers monitor consumption, but the psychological shift is real—no more unlimited AI for a flat fee. For individual developers, this means being more deliberate about when to use Copilot versus writing code manually. For teams, it introduces budgeting complexity. The removal of Opus models from Pro plans further limits options for users who wanted cutting-edge performance. The broader implication is that the era of cheap, unlimited AI coding assistants is ending. Developers should explore alternatives like Mistral's Vibe VS Code extension (launched May 28) or local models like Gemma 4 12B for offline coding assistance. If you're a solo developer, consider whether the new pricing still makes sense for your workflow, or if a local model could replace Copilot entirely.
Meldung 4
OpenAI Retires GPT-4.5 and o3, Upgrades GPT-5.5 Instant
OpenAI updated GPT-5.5 Instant with more accurate responses and a natural writing style, while announcing the retirement of GPT-4.5 on June 27 and o3 on August 26 from ChatGPT for paid users. The company also deprecated reusable prompt objects, the Evals platform, and Agent Builder, with shutdowns by November 30, 2026.
Florians EinordnungOpenAI is cleaning house. If you're still using GPT-4.5 or o3, you have a hard deadline to migrate. This is also a warning not to over-invest in beta features that might get deprecated.
Für deinen Alltag Identify any OpenAI beta features or deprecated models in your stack and migrate to GPT-5.5 Instant or alternative providers before the deadlines.
Ganzen Artikel lesen
OpenAI's announcement on June 4 to retire GPT-4.5 and o3 marks a clear consolidation strategy. GPT-5.5 Instant, which now powers the default experience, has been upgraded with more accurate responses and a natural writing style—effectively making the older models redundant. GPT-4.5 will be removed from ChatGPT for paid users on June 27, and o3 on August 26. More concerning for developers is the deprecation of reusable prompt objects, the Evals platform, and Agent Builder, all shutting down by November 30, 2026. Additionally, older GPT Image models (gpt-image-1-mini, gpt-image-1.5) will be removed from the API on December 1, with gpt-image-2 as the recommended replacement. This is a classic platform risk: features you build on today can disappear tomorrow. For teams using OpenAI's ecosystem, this means auditing every integration for deprecated dependencies. The Evals platform shutdown is particularly painful for teams that built custom evaluation pipelines. The lesson: diversify your AI stack. Consider using open-source models like Gemma 4 for critical workflows, or at minimum, abstract your API calls so you can switch providers quickly. OpenAI is moving fast, and if you're locked into their proprietary tools, you're exposed.
Prompt des Tages
Local AI Dev Setup
Act as an AI deployment engineer. Given that Gemma 4 12B fits in 16GB VRAM and runs on macOS and mobile, write a step-by-step guide for setting up a local multimodal AI workflow that processes images and audio without cloud dependencies. Include hardware requirements, installation commands, and a test script. Output in plain text with numbered steps.
Use this when you want to prototype local AI apps without paying API costs or sending data to the cloud.
Deep Dive
How to Migrate from Llama to Gemma 4 12B in One Afternoon
With Meta closing Llama weights for Muse Spark, developers who built on Llama need a migration plan. Gemma 4 12B is the most practical alternative right now because it runs on local hardware (16GB VRAM) and is fully open-weight. Here's how to make the switch in a single afternoon. First, assess your dependency. If you were using Llama via an API (like Meta's or a third-party), you need to find every endpoint call. Search your codebase for 'llama', 'meta-llama', and 'LlamaTokenizer'. If you were running Llama locally, you need to download Gemma 4 12B from Hugging Face or Google's AI Edge Gallery. The model is about 24GB in size, so ensure you have storage and a GPU with at least 16GB VRAM. For macOS users with Apple Silicon, the unified memory architecture handles this well—test with the Eloquent app first. Second, update your inference code. Gemma uses a different tokenizer and input format. For text-only tasks, the change is minimal: replace 'model_name = "meta-llama/Llama-2-7b"' with 'model_name = "google/gemma-4-12b-it"' and adjust the prompt template. Gemma expects a specific chat format: '<start_of_turn>user\nYour prompt here<end_of_turn>\n<start_of_turn>model\n'. For multimodal tasks, Gemma's architecture is actually simpler because it removes encoders. You pass raw audio waveforms or image tensors directly. Third, benchmark your key workflows. Run your existing test suite and compare output quality. Gemma 4 12B matches Llama 3 70B on many benchmarks but may differ in style. If you need exact behavior, consider fine-tuning Gemma using Mistral's new fine-tuning API or LoRA adapters. Finally, update your deployment pipeline. If you were using Docker containers, swap the base image. If you were using cloud endpoints, switch to a Gemma-compatible serving stack like vLLM or TokenSpeed (which just hit 580 tokens per second for agentic workloads). The migration should take 2-4 hours for most projects. The payoff is independence from Meta's closed ecosystem and the ability to run entirely offline.
The open-source AI party is over. Build on models you can actually run yourself.
Für Ihren Betrieb
Welcher Ablauf lohnt sich bei Ihnen zuerst?
Mit dem kostenlosen KI-Prozess-Check sehen Sie in 15 Minuten, wo in Ihrem Betrieb die meiste Zeit liegen bleibt. Oder wir sehen es uns in 30 Minuten gemeinsam an, kostenlos und ohne Verkaufsgespräch.