Archiv-Ausgabe vor Einführung der QuellenprüfungDiese Ausgabe ist vor dem 17. Oktober 2026 entstanden und wurde nicht nachträglich geprüft. Sie kann Fehler oder überholte Angaben enthalten. Für Entscheidungen bitte die verlinkten Originalquellen lesen.
In einer Minute im Bild
Anthropic released Claude Fable 5 at half the cost of Mythos Preview, scoring 80.3% on SWE-Bench Pro and dominating GPT-5.5 and Opus 4.8.
Google signed a $920M/month deal with SpaceX for 110,000 NVIDIA GPUs, signaling AI compute demand is entering a new stratosphere.
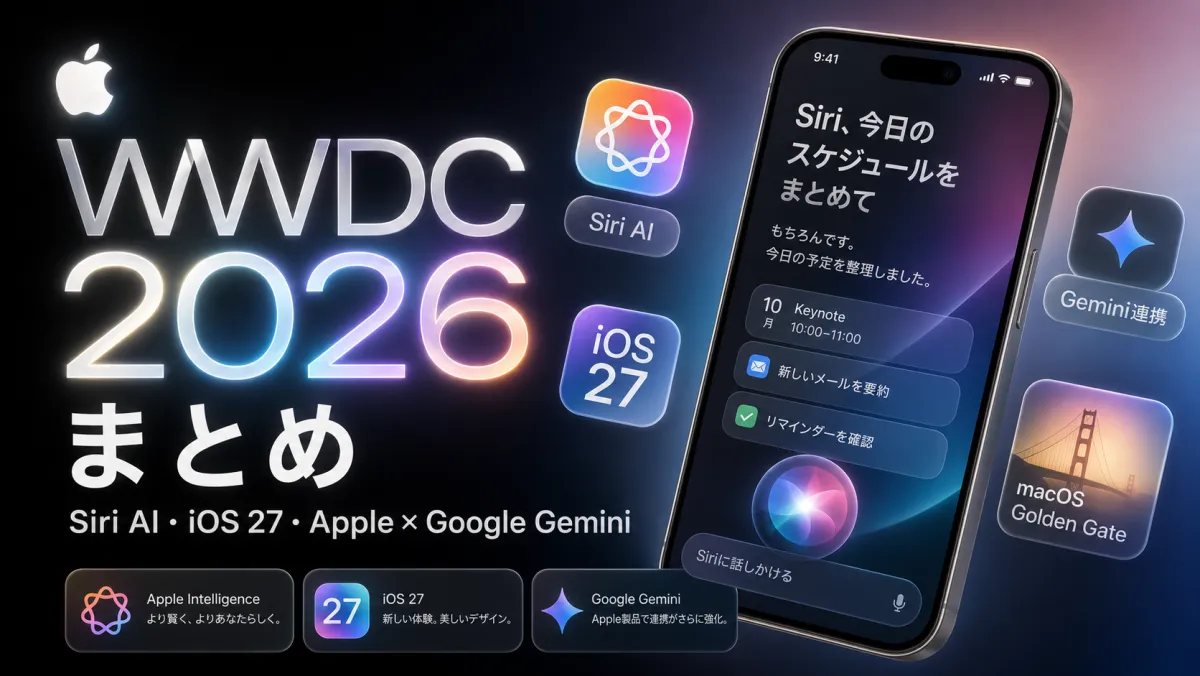
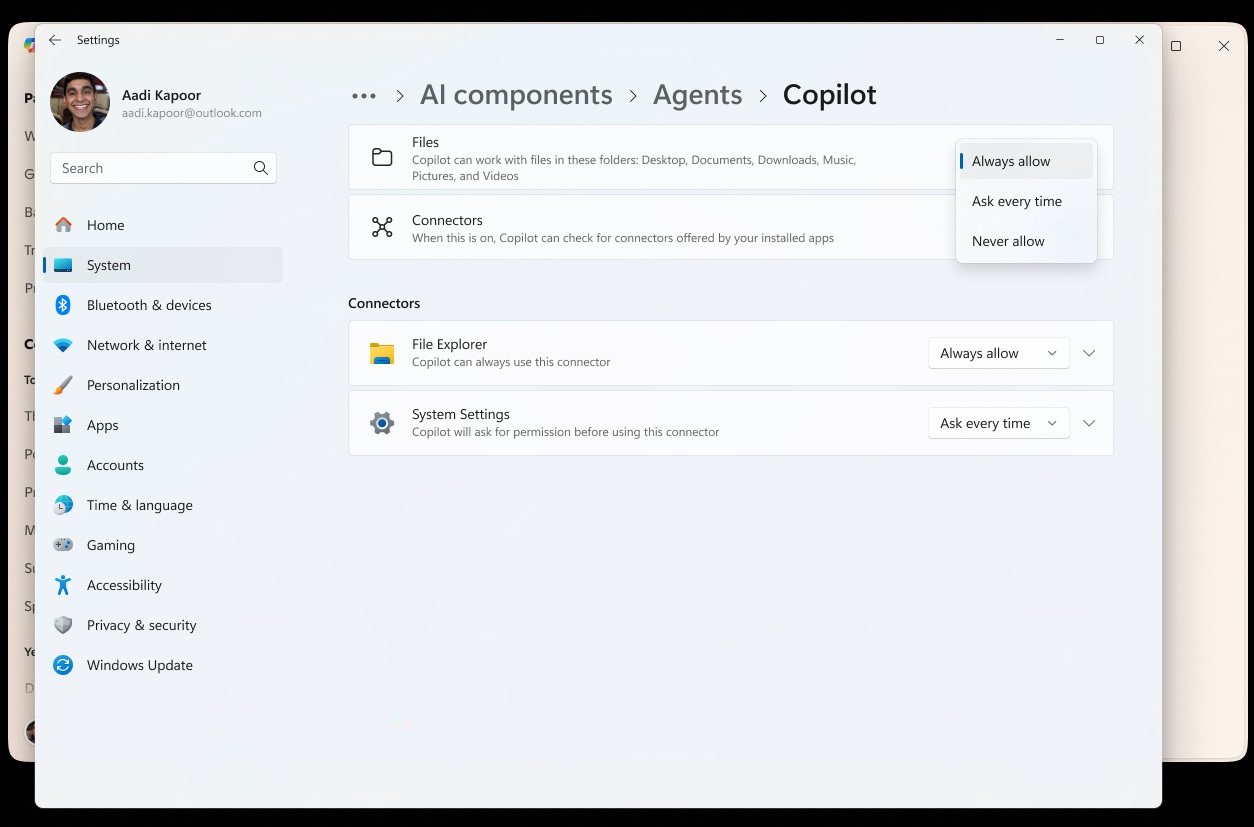
Apple integrated Google Gemini into a rebuilt Siri at WWDC, while Microsoft announced Windows is becoming an AI-native OS for autonomous agents.
Meldung 1
Claude Fable 5 crushes benchmarks at half price
Anthropic launched Claude Fable 5, its first generally available Mythos-class model, scoring 80.3% on SWE-Bench Pro—beating GPT-5.5 (58.6%) and Claude Opus 4.8 (69.2%). It costs $10/M input tokens and $50/M output tokens, less than half the price of Mythos Preview.
Florians EinordnungFable 5 isn't just good—it's a price-performance revolution. If you're paying for Opus 4.8 or GPT-5.5, you're leaving money and accuracy on the table.
Für deinen Alltag Migrate your production eval pipeline to Claude Fable 5 before June 22 to lock in free testing and assess the 11-point SWE-Bench advantage over your current model.
Ganzen Artikel lesen
Anthropic dropped two bombs today: Claude Fable 5, their first Mythos-class model available to everyone, and Claude Mythos 5, which lifts safeguards for vetted cyberdefenders. Fable 5's 80.3% on SWE-Bench Pro isn't just a number—it's 11 points higher than Opus 4.8 and 22 points above GPT-5.5. That's not incremental; that's a generational leap.
The pricing is the real story. At $10/M input and $50/M output, Fable 5 costs less than half of Mythos Preview. For context, GPT-5.5 costs roughly $15/M input and $60/M output. Anthropic just made frontier intelligence cheaper than last-gen models. The 1M-token context window and 128k output tokens mean you can feed it entire codebases and get back full implementations.
Availability spans Claude API, AWS Bedrock, Vertex AI, and Microsoft Foundry. Free access for Pro/Max/Team plans runs until June 22—that's your window to test without spending a dime. If you're building developer tools, coding assistants, or any application where code quality matters, switch your eval pipeline to Fable 5 today.
The strategic implication is clear: Anthropic is winning the price-performance war. Google and OpenAI will need to respond, but for now, Fable 5 is the default choice for serious AI engineering work.
Meldung 2
Google rents 110,000 GPUs from SpaceX at $920M/month
Google signed a deal with SpaceX to rent 110,000 NVIDIA GPUs for AI compute, running from October 2026 to June 2029. The deal serves as a bridging solution while Google scales its own TPU infrastructure.
Florians EinordnungWhen Google—the company with the most AI compute on Earth—has to rent GPUs from a rocket company, you know the shortage is real. This isn't a flex; it's a distress signal.
Für deinen Alltag Optimize your inference pipeline for efficiency now—compute costs will remain high through 2029, and the hyperscalers are already fighting over supply.
Ganzen Artikel lesen
Google's $920 million per month deal with SpaceX for 110,000 NVIDIA GPUs is the single largest compute lease in history. Let that sink in: nearly a billion dollars a month, going to a company whose primary business is launching satellites. This is what AI compute scarcity looks like at the highest level.
The deal runs from October 2026 to June 2029—almost three years. That's Google admitting their internal TPU supply chain can't keep pace with demand. They're paying a premium to bridge the gap until they can manufacture enough custom silicon. For context, 110,000 H100-equivalent GPUs could train a GPT-5-class model in weeks.
What this means for builders: compute isn't getting cheaper. If the hyperscalers are fighting over scraps, you need to optimize. Quantize your models. Use speculative decoding. Consider on-device inference. The era of 'throw more GPUs at it' is over for everyone except the top 5 companies.
Second-order effects: SpaceX now has a massive incentive to build more data center capacity. This could accelerate their Starshield and satellite compute ambitions. Also, expect NVIDIA's next earnings to be absurd. And if you're a startup building AI infrastructure, this is your signal that demand will outstrip supply for at least 3 more years.
Meldung 3
Apple rebuilds Siri with Gemini at WWDC
Apple announced a rebuilt Siri powered by Apple Intelligence, with Google Gemini handling parts of the new system. Xcode 27 introduces agentic coding with models from Anthropic, Google, and OpenAI.
Florians EinordnungApple finally admitting they can't do AI alone and partnering with Google is the biggest strategic shift since the iPhone. The walled garden just opened a door.
Für deinen Alltag Start experimenting with Apple's new intelligence frameworks and Xcode 27 agentic coding—the barrier to shipping AI features on iOS just dropped dramatically.
Ganzen Artikel lesen
WWDC 2026 delivered what Apple has been avoiding for years: a real AI strategy. The rebuilt Siri uses Apple Intelligence as the foundation but taps Google Gemini for heavy lifting. This is Apple admitting that their in-house models aren't competitive at the frontier—and choosing pragmatism over pride.
Xcode 27 is the bigger story for developers. It introduces agentic coding with integrated models from Anthropic, Google, and OpenAI. You can interactively plan, do multi-turn Q&A, and make real-time code changes. The new intelligence frameworks provide a single native Swift API for both on-device and server models. This means you can write iOS apps that seamlessly switch between local and cloud AI without managing infrastructure.
For Apple ecosystem developers, this is a gold rush. The barrier to adding AI features just dropped to 'write a Swift function.' The Gemini integration means Siri can finally handle complex queries, and the agentic coding in Xcode will make you faster—if you learn the new tools.
The strategic play: Apple is commoditizing the AI model layer. By supporting multiple providers through a unified API, they ensure no single company (including Google) has leverage over them. It's the same playbook they used with chip suppliers—diversify and control the integration point.
Meldung 4
Windows becomes AI-native OS for agents
Microsoft announced Windows is evolving into an AI-native operating system designed for autonomous agents, with agentic AI positioned as the next major computing platform.
Florians EinordnungMicrosoft is betting the entire Windows franchise on agents. If they pull it off, it's a new era. If they fail, it's Windows Vista 2.0.
Für deinen Alltag If you build enterprise software, learn Copilot Studio and start prototyping agent workflows—Windows is about to become an agent operating system.
Ganzen Artikel lesen
At Microsoft Build, the company made its biggest bet since the cloud: Windows is becoming an AI-native OS. Not 'AI features in Windows'—the OS itself is being rebuilt around autonomous agents. Think of it as Windows becoming a platform where AI agents are first-class citizens, alongside files, apps, and the web.
The key components: Microsoft Agent 365 is being adopted by KPMG to manage and monitor AI agent deployment at scale. Copilot Studio got upgrades for advanced orchestration and automation. The vision is that your OS doesn't just run apps—it runs agents that run tasks for you.
For developers, this means building Windows applications will increasingly mean building agents. The Copilot Studio upgrades allow you to create complex multi-step workflows that span Office 365, Azure, and third-party services. KPMG's adoption is a signal that enterprise compliance and governance for agents is becoming a real product category.
The risk: Microsoft has a history of overcomplicating things (remember Cortana?). If the agent platform is too complex, developers will build for web and mobile instead. But if they nail the developer experience, Windows could become the default platform for enterprise AI automation.
Prompt des Tages
Agentic Code Review
You are a senior software engineer. Review the following pull request for security vulnerabilities, performance issues, and code style violations. Provide a bulleted list of issues ranked by severity, with specific line references and suggested fixes. Do not praise code—only critique what needs to change.
Use this when you need a no-fluff, actionable code review from an AI agent that treats you like a peer, not a student.
Deep Dive
How to Optimize Your AI Inference Costs for the Fable 5 Era
Claude Fable 5's pricing is a wake-up call. At $10/M input and $50/M output, it's cheaper than models with half its capability. But cheap is relative—if you're running millions of calls a day, even these prices add up. Here's how to optimize without sacrificing quality.
First, use prompt caching aggressively. Anthropic supports prompt caching on their API, which can reduce input token costs by up to 90% for repeated system prompts or context. If you're sending the same codebase context with every request, cache it. This is the single biggest lever for cost reduction.
Second, implement speculative decoding and output streaming. Fable 5 supports up to 128k output tokens, but you rarely need all of them. Set reasonable max_tokens limits and use streaming to process results incrementally. This reduces the effective cost per task because you're not paying for tokens you don't use.
Third, batch your requests. The API pricing is per-token, but many providers offer discounted batch rates. If your workload can tolerate latency (e.g., nightly code reviews, batch documentation generation), queue requests and process them together. This can cut costs by 30-50%.
Fourth, use the 1M-token context window strategically. Instead of making multiple calls with partial context, pack your entire codebase into a single call. Fewer requests mean fewer output tokens and lower overhead. Just be careful with context window utilization—filling it to 100% is rarely optimal.
Finally, monitor your token usage per task. Most teams don't know their token economics. Set up logging for input and output tokens per API call, then calculate cost per completed task. You'll likely find that 20% of your use cases consume 80% of your budget. Optimize those first.
Fable 5 is cheap for frontier AI, but it's not free. Treat it like cloud compute: measure, optimize, and automate. The teams that do this well will build products that competitors can't afford to run.
Fable 5 is cheap, GPUs are scarce, and Apple finally learned to ask for help. Adapt or get left behind.
Für Ihren Betrieb
Welcher Ablauf lohnt sich bei Ihnen zuerst?
Mit dem kostenlosen KI-Prozess-Check sehen Sie in 15 Minuten, wo in Ihrem Betrieb die meiste Zeit liegen bleibt. Oder wir sehen es uns in 30 Minuten gemeinsam an, kostenlos und ohne Verkaufsgespräch.