Archiv-Ausgabe vor Einführung der QuellenprüfungDiese Ausgabe ist vor dem 17. Oktober 2026 entstanden und wurde nicht nachträglich geprüft. Sie kann Fehler oder überholte Angaben enthalten. Für Entscheidungen bitte die verlinkten Originalquellen lesen.
In einer Minute im Bild
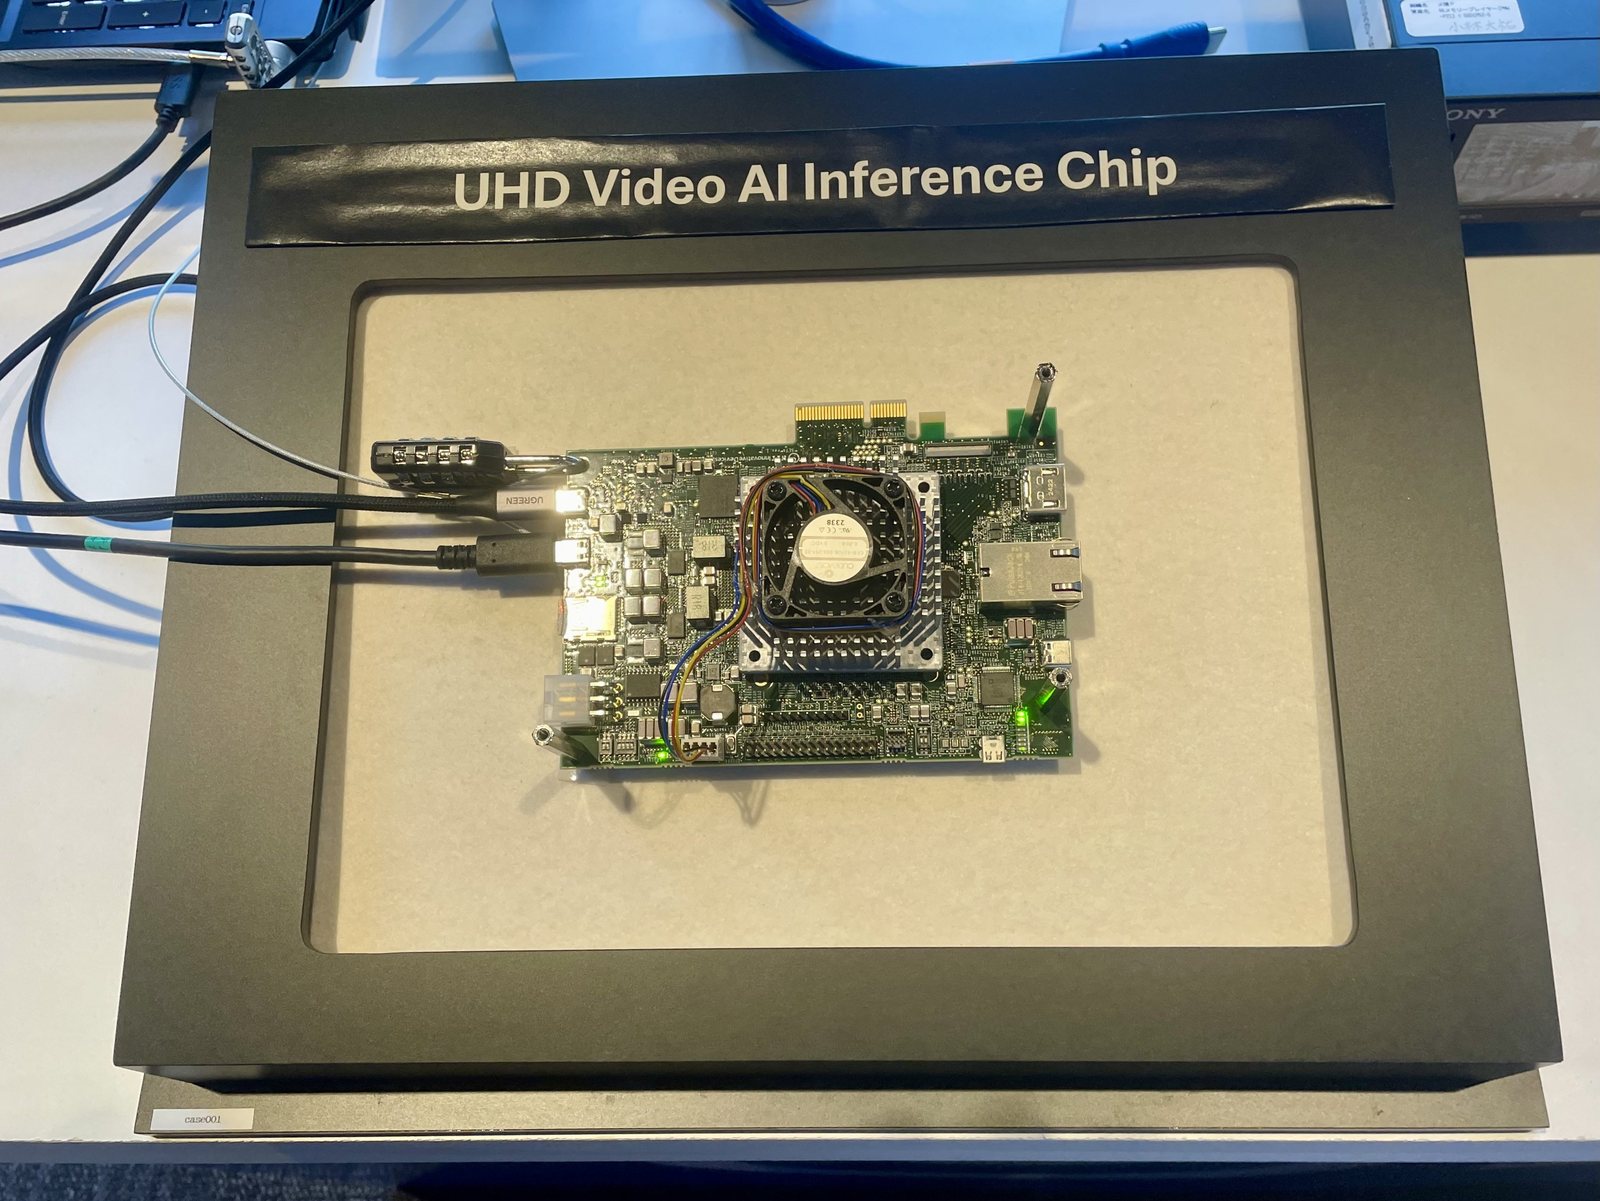
OpenAI shipped its custom Jalapeño inference chip with Broadcom for gigawatt-scale LLM serving starting late 2026.
Qualcomm acquired Modular for $4B to break hardware lock-in, letting devs run AI models across any chip without rewrites.
GPT-5.5 Instant got a major update improving intent understanding and shopping/local recommendations for paid and free users.
The EU approved AI Act amendments delaying high-risk obligations to 2027 and banning non-consensual nudifier apps by December 2026.
Meldung 1
OpenAI unveils Jalapeño AI inference chip
OpenAI revealed its first custom AI inference chip, built with Broadcom, optimized for LLM token serving with better performance per watt. It's a multi-generation platform for gigawatt-scale data centers starting late 2026.
Florians EinordnungThis is OpenAI's play to own the stack from silicon to API. If they pull it off, watch for cost drops and tighter integration that rivals can't match.
Für deinen Alltag Start monitoring OpenAI's pricing changes post-Jalapeño rollout to adjust your inference budget.
Ganzen Artikel lesen
OpenAI's Jalapeño chip is purpose-built for inference, not training, targeting the massive compute demand of serving models like GPT-5.5 at scale. Partnering with Broadcom gives them manufacturing and networking expertise to deploy at hyperscale. The chip is designed for multi-generation deployment, meaning future iterations will improve without a complete architectural overhaul. For builders, this could translate to lower API costs and faster response times as OpenAI reduces dependency on third-party hardware. However, it also tightens OpenAI's grip on the ecosystem—if you're building on their API, you're betting on their hardware roadmap. The first deployments target late 2026, so don't expect immediate changes, but start planning for a world where inference costs could drop significantly.
Meldung 2
Qualcomm buys Modular for $4B
Qualcomm acquired Modular, an AI infrastructure startup, for $4 billion. Modular's software lets developers run AI models across diverse chips without extensive code rewriting, challenging hardware lock-in.
Florians EinordnungQualcomm just bought the key to making AI hardware-agnostic. If they execute, developers win—but it's a long bet against Nvidia's CUDA moat.
Für deinen Alltag If you're locked into one hardware vendor, start prototyping with Modular's tools to future-proof your stack.
Ganzen Artikel lesen
Modular's value is in its abstraction layer: write once, run on any chip—GPU, CPU, NPU, or custom hardware. This directly threatens Nvidia's lock-in, where CUDA-optimized code doesn't easily port to competitors. Qualcomm is betting that the future of AI is heterogeneous hardware, and they want to be the middleware that makes it seamless. For developers, this means more flexibility: you could deploy on Qualcomm's edge chips, cloud GPUs, or even upcoming custom silicon without rewriting. The $4B price tag reflects the strategic importance of breaking the current dependency. However, integration risk is real—Qualcomm has a mixed track record with acquisitions. Watch for Modular's tools to appear in Qualcomm's AI Hub and developer SDKs over the next 12 months.
Meldung 3
GPT-5.5 Instant update improves understanding
OpenAI rolled out a significant update to GPT-5.5 Instant, improving user intent understanding, complex constraint handling, and shopping/local recommendations. Available to paid users June 25 and free users June 26.
Florians EinordnungThis update makes GPT-5.5 Instant actually useful for real-world tasks like planning and recommendations. Free users finally get a taste of what paid users have had for a day.
Für deinen Alltag Update your API calls to use the chat-latest alias to get this improvement immediately.
Ganzen Artikel lesen
The update focuses on three areas: understanding what you really mean (intent), handling multiple constraints simultaneously (e.g., 'find a vegan restaurant under $20 within 2 miles'), and better shopping and local recommendations. The fact that it's also available via the chat-latest API alias means builders can immediately integrate it into their apps. For end users, this is the first time GPT-5.5 feels like a competent assistant for everyday decisions rather than just a text generator. The rollout is staggered—paid users got it on June 25, free users on June 26—so if you're on the free tier and still seeing old behavior, it may take a few hours to propagate. For developers, this is a reminder to test the chat-latest endpoint regularly; OpenAI is shipping fast, and your app should too.
Meldung 4
EU AI Act amendments approved
The European Parliament approved amendments delaying high-risk AI system obligations to December 2, 2027, and watermarking obligations to December 2, 2026. Nudifier apps creating non-consensual explicit content become prohibited on December 2, 2026.
Florians EinordnungThe EU gave builders breathing room on high-risk rules, but the nudifier ban is a hard deadline. If your product touches synthetic media, get compliant now.
Für deinen Alltag Audit your AI product for watermarking and safety features before the EU's December 2026 deadlines.
Ganzen Artikel lesen
The amendments push back the most onerous compliance requirements, giving companies more time to adapt. High-risk AI obligations now land in December 2027, not earlier, which is a win for startups and enterprises still building their governance frameworks. Watermarking requirements are due December 2026, so if your model generates images, video, or text, you need a watermarking solution within six months. The nudifier ban is immediate and absolute—any app that creates non-consensual sexually explicit content is illegal as of December 2, 2026. This is a clear signal that the EU is serious about AI safety, but also pragmatic about giving industry time to adjust. For builders, the takeaway is simple: start implementing transparency measures now, and if your app could be used for harmful deepfakes, proactively add guardrails.
Prompt des Tages
Shopping Recommender
You are a local shopping assistant. Given a user's intent and location, recommend 3 specific stores or products with reasoning. Constraints: prioritize local businesses, use real-time data if available, and explain why each choice fits the user's needs.
Use when you need GPT-5.5 Instant's improved shopping and local recommendation capabilities.
Deep Dive
Building Hardware-Agnostic AI Pipelines
With Qualcomm's acquisition of Modular and OpenAI's custom chip, the era of hardware lock-in is ending—but only if you design your pipeline to be portable. The key insight is that inference performance depends less on the chip and more on the software stack that sits between your model and the hardware. Modular's approach uses a compiler-based abstraction that converts model graphs into optimized code for any target. To build hardware-agnostic pipelines today, start by using frameworks like ONNX or TensorRT that support multiple backends. Avoid writing custom CUDA kernels unless absolutely necessary, because they tie you to Nvidia. Instead, use high-level APIs like PyTorch's torch.compile or TensorFlow's XLA, which can target different accelerators. Next, containerize your inference server with Docker so you can deploy on any cloud or edge device. Use Kubernetes for orchestration, which abstracts the underlying hardware from your application logic. Finally, benchmark your model on at least two different hardware types (e.g., Nvidia A100 and AMD MI300) to verify performance portability. The goal is to make your AI stack as easy to move as a web app—write once, deploy anywhere. This is exactly what Modular enabled, and now Qualcomm will push it further. If you start now, you'll be ready when the next hardware shift happens.
Build for the stack you want, not the stack you have.
Für Ihren Betrieb
Welcher Ablauf lohnt sich bei Ihnen zuerst?
Mit dem kostenlosen KI-Prozess-Check sehen Sie in 15 Minuten, wo in Ihrem Betrieb die meiste Zeit liegen bleibt. Oder wir sehen es uns in 30 Minuten gemeinsam an, kostenlos und ohne Verkaufsgespräch.