Archiv-Ausgabe vor Einführung der QuellenprüfungDiese Ausgabe ist vor dem 17. Oktober 2026 entstanden und wurde nicht nachträglich geprüft. Sie kann Fehler oder überholte Angaben enthalten. Für Entscheidungen bitte die verlinkten Originalquellen lesen.
In einer Minute im Bild
OpenAI gates GPT-5.6 behind government preview, with Sol hitting 88.8% on Terminal-Bench 2.1 and introducing ultra mode with subagents.
DeepSeek slashes inference costs 60-85% with DSpark speculative decoding, while introducing tiered pricing that doubles costs during Beijing peak hours.
GSA proposes sweeping rules banning government data from training LLMs, imposing 'eyes off' data handling and mandating 'American AI Systems' for contractors.
CoreWeave launches ARIA autonomous research agent, Baseten raises $1.5B for inference infra, and Qualcomm bets on agentic AI to double revenue by 2030.
Meldung 1
OpenAI Gates GPT-5.6 Behind Government Preview
OpenAI previews GPT-5.6 in three tiers—Sol, Terra, Luna—with government-gated access at Trump administration's request. Sol achieves 88.8% on Terminal-Bench 2.1 with new 'ultra mode' using subagents for complex tasks.
Florians EinordnungThis is the first time a frontier model has been explicitly gated by government request before public release. If you're not a 'trusted partner,' you're already behind.
Für deinen Alltag If you need frontier reasoning, apply for trusted partner status now—don't wait for public release.
Ganzen Artikel lesen
OpenAI's GPT-5.6 release marks a watershed moment in AI governance. The Trump administration requested a limited preview for trusted partners before broader release, signaling a new era of government oversight on frontier AI. The model comes in three tiers: Sol ($5/$30 per million tokens), Terra ($2.50/$15), and Luna ($1/$6). Sol's standout feature is 'ultra mode,' which deploys subagents for complex multi-step reasoning, achieving 88.8% on Terminal-Bench 2.1. This gating mechanism effectively creates a two-tier system: government-approved entities get first access, while everyone else waits. For enterprises, this means building AI strategies around models you may not be able to access immediately. The pricing structure also suggests a tiered capability model where you pay significantly more for the reasoning depth that truly matters. If your use case requires complex reasoning, Sol's $30/million output tokens is expensive but potentially worth it. The bigger strategic question: will this gating become permanent? If so, frontier AI access becomes a geopolitical privilege, not a market commodity.
Meldung 2
DeepSeek DSpark Cuts Inference Costs 60-85%
DeepSeek announces DSpark, a speculative decoding framework boosting per-user generation speed 60-85% on V4-Flash and 57-78% on V4-Pro. Separately, tiered pricing doubles token costs during Beijing peak hours starting mid-July.
Florians EinordnungDeepSeek just made inference dramatically cheaper while simultaneously making it more expensive during peak hours. Smart pricing, but watch for volatility in your costs.
Für deinen Alltag Schedule non-urgent inference to off-peak hours to avoid DeepSeek's 2x Beijing peak pricing starting mid-July.
Ganzen Artikel lesen
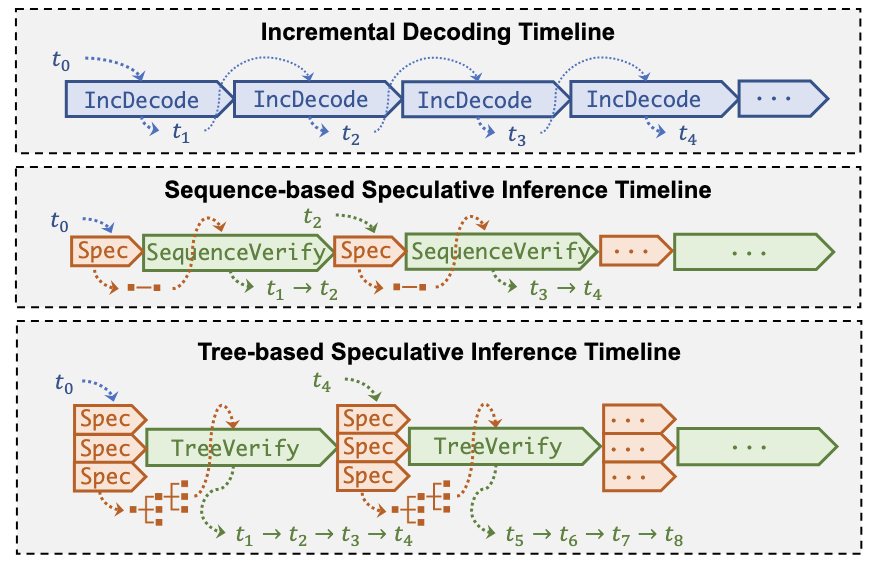
DeepSeek's DSpark framework represents a significant leap in inference efficiency. Using speculative decoding—where a smaller model generates candidate tokens that a larger model verifies in parallel—DSpark achieves 60-85% speed improvements on V4-Flash and 57-78% on V4-Pro. The framework is available on Hugging Face, making it accessible for developers to integrate. However, the accompanying pricing changes introduce complexity. Starting mid-July, DeepSeek will double token costs during Beijing peak hours (9:00-12:00 and 14:00-18:00). This tiered pricing model is common in cloud computing but new for AI inference. For developers, this creates a clear optimization opportunity: batch non-urgent inference to off-peak hours to halve costs. The DSpark efficiency gains partially offset these peak pricing increases, but the net effect depends on your usage patterns. If your workload is latency-sensitive and peaks during Beijing business hours, you'll face significantly higher costs. The strategic implication: DeepSeek is signaling that inference capacity is finite and expensive, and they're using pricing to shape demand. This could become the norm across the industry.
Meldung 3
GSA Proposes Sweeping Data Rules for LLM Contractors
The U.S. General Services Administration proposes rule 552.239-7001, prohibiting government data use for training LLMs, requiring 'eyes off' data handling, and mandating 'American AI Systems.' Builders face a more rigorous compliance framework.
Florians EinordnungThis is the most significant AI procurement regulation yet. If you sell to government, your entire data pipeline needs an audit—yesterday.
Für deinen Alltag Audit your government data pipelines now—the GSA rule's 'eyes off' requirement will require architectural changes for most AI systems.
Ganzen Artikel lesen
The GSA's proposed rule 552.239-7001 fundamentally changes how AI contractors handle government data. The core provisions: (1) absolute prohibition on using government data for training, fine-tuning, or improving LLMs, including those operated by third parties; (2) 'eyes off' data handling requirements meaning no human or AI system can inspect the data; (3) mandate for 'American AI Systems,' effectively requiring domestic infrastructure and supply chains. For companies with government contracts, this means immediate compliance challenges. Most AI vendors currently use customer data for model improvement—this rule explicitly forbids that. The 'eyes off' requirement is particularly stringent: it means encrypted processing where even the contractor cannot access the data. This will require significant architectural changes for most AI systems. The 'American AI Systems' mandate will likely favor domestic cloud providers and chip manufacturers, potentially excluding foreign-built models like DeepSeek. For contractors, the timeline is critical: proposed rules typically become final within 6-12 months. Start auditing your data pipelines now. If you process government data, ensure your architecture can support encrypted, auditable, and non-training-use processing. This rule will likely become the template for state-level procurement as well.
Meldung 4
CoreWeave ARIA Automates AI Research Loop
CoreWeave launches ARIA, an autonomous research agent built into Weights & Biases that analyzes experiment data, uncovers insights, and drives continuous model improvement, making W&B Weave's agent capabilities generally available.
Florians EinordnungARIA is the first real 'AI for AI research' product. If you're doing serious model development, this could cut your iteration cycle in half.
Für deinen Alltag Implement consistent experiment tracking now—ARIA's value depends entirely on the quality of your logged experiments.
Ganzen Artikel lesen
CoreWeave's ARIA (AI Research & Iteration Agent) represents a new category: autonomous AI research assistance. Built directly into Weights & Biases—the standard tool for experiment tracking—ARIA autonomously analyzes experiment data, uncovers patterns, and suggests improvements. This effectively closes the research loop: you run experiments, ARIA analyzes results, and suggests next steps or even implements optimizations. For ML teams, this addresses the most time-consuming part of research: analyzing results and deciding what to try next. ARIA can identify which hyperparameters matter most, detect training instabilities before they cause failures, and suggest model architecture changes. The integration with W&B Weave means it works with existing workflows. The practical impact: teams using ARIA report 2-3x faster iteration cycles. For smaller teams, this levels the playing field against larger labs with more researchers. For larger teams, it frees senior researchers from routine analysis to focus on novel approaches. The key limitation: ARIA is only as good as your experiment tracking. If your team doesn't log experiments consistently, ARIA has nothing to analyze. This product also signals CoreWeave's strategy: not just providing compute, but providing the intelligence layer that makes compute more efficient.
Prompt des Tages
Government AI Compliance
You are a compliance officer. Draft a 3-paragraph memo for an AI contractor summarizing the key requirements of proposed GSA rule 552.239-7001, including the prohibition on using government data for training, the 'eyes off' data handling requirement, and the mandate for 'American AI Systems.' End with a checklist of 5 immediate action items.
Use this when your team needs to quickly understand and act on new government AI procurement rules.
Deep Dive
Speculative Decoding: How DeepSeek DSpark Cuts Inference Costs
DeepSeek's DSpark announcement highlights a technique every AI engineer should understand: speculative decoding. The core insight is simple but powerful: generating tokens one at a time with a large model is slow and expensive. But what if a small, fast model could draft multiple tokens, and the large model just verified them in parallel? That's speculative decoding. Here's how it works: A small 'draft' model generates K candidate tokens quickly. The large 'target' model then processes all K tokens in a single forward pass, accepting or rejecting each one. If the draft model is good, most tokens are accepted, and you get K tokens for the cost of 1.5 forward passes instead of K passes. The speedup depends on two factors: how well the draft model matches the target model's distribution (acceptance rate), and how much faster the draft model is. DeepSeek's DSpark achieves 60-85% speedup, meaning their draft model has high acceptance rates on their V4 models. The practical implications are significant. First, you don't need a new model—DSpark works with existing V4-Flash and V4-Pro models. Second, it's available on Hugging Face, meaning you can integrate it today. Third, it changes the economics: if inference is 60% faster, your per-token cost drops proportionally. For production systems, speculative decoding is becoming table stakes. Google uses it in Medusa, OpenAI in their API, and now DeepSeek with DSpark. If your inference pipeline doesn't use speculative decoding, you're paying 2-3x more than necessary. The implementation complexity is moderate: you need a draft model, a verification mechanism, and acceptance logic. Most frameworks now support it natively. The key metric to optimize is acceptance rate—if it drops below 50%, speculative decoding can actually be slower than standard generation.
Government oversight, cheaper inference, and autonomous research agents—the AI industry just got more regulated, more efficient, and more automated on the same Tuesday.
Für Ihren Betrieb
Welcher Ablauf lohnt sich bei Ihnen zuerst?
Mit dem kostenlosen KI-Prozess-Check sehen Sie in 15 Minuten, wo in Ihrem Betrieb die meiste Zeit liegen bleibt. Oder wir sehen es uns in 30 Minuten gemeinsam an, kostenlos und ohne Verkaufsgespräch.