Mistral-Reason-7B: open-source reasoning model beats Llama-3-8B
5 Meldungenca. 6 Min. LesezeitArchiv · ungeprüft
Archiv-Ausgabe vor Einführung der QuellenprüfungDiese Ausgabe ist vor dem 17. Oktober 2026 entstanden und wurde nicht nachträglich geprüft. Sie kann Fehler oder überholte Angaben enthalten. Für Entscheidungen bitte die verlinkten Originalquellen lesen.
In einer Minute im Bild
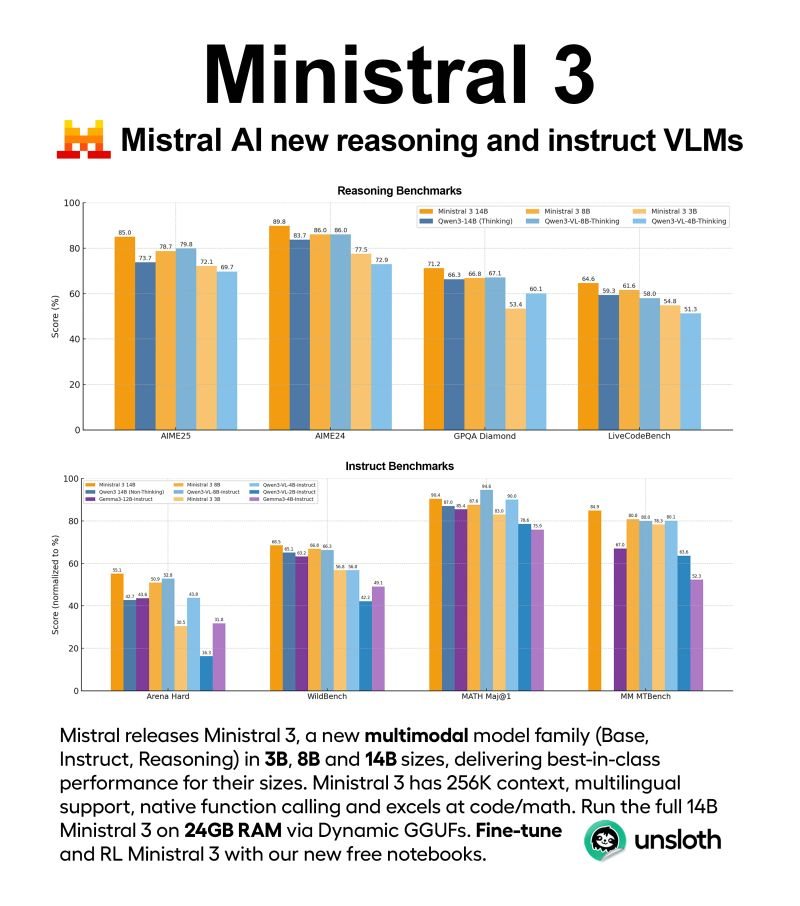
Mistral releases Mistral-Reason-7B, an open-source reasoning model that outperforms Llama-3-8B by 12% on math benchmarks and runs on consumer GPUs.
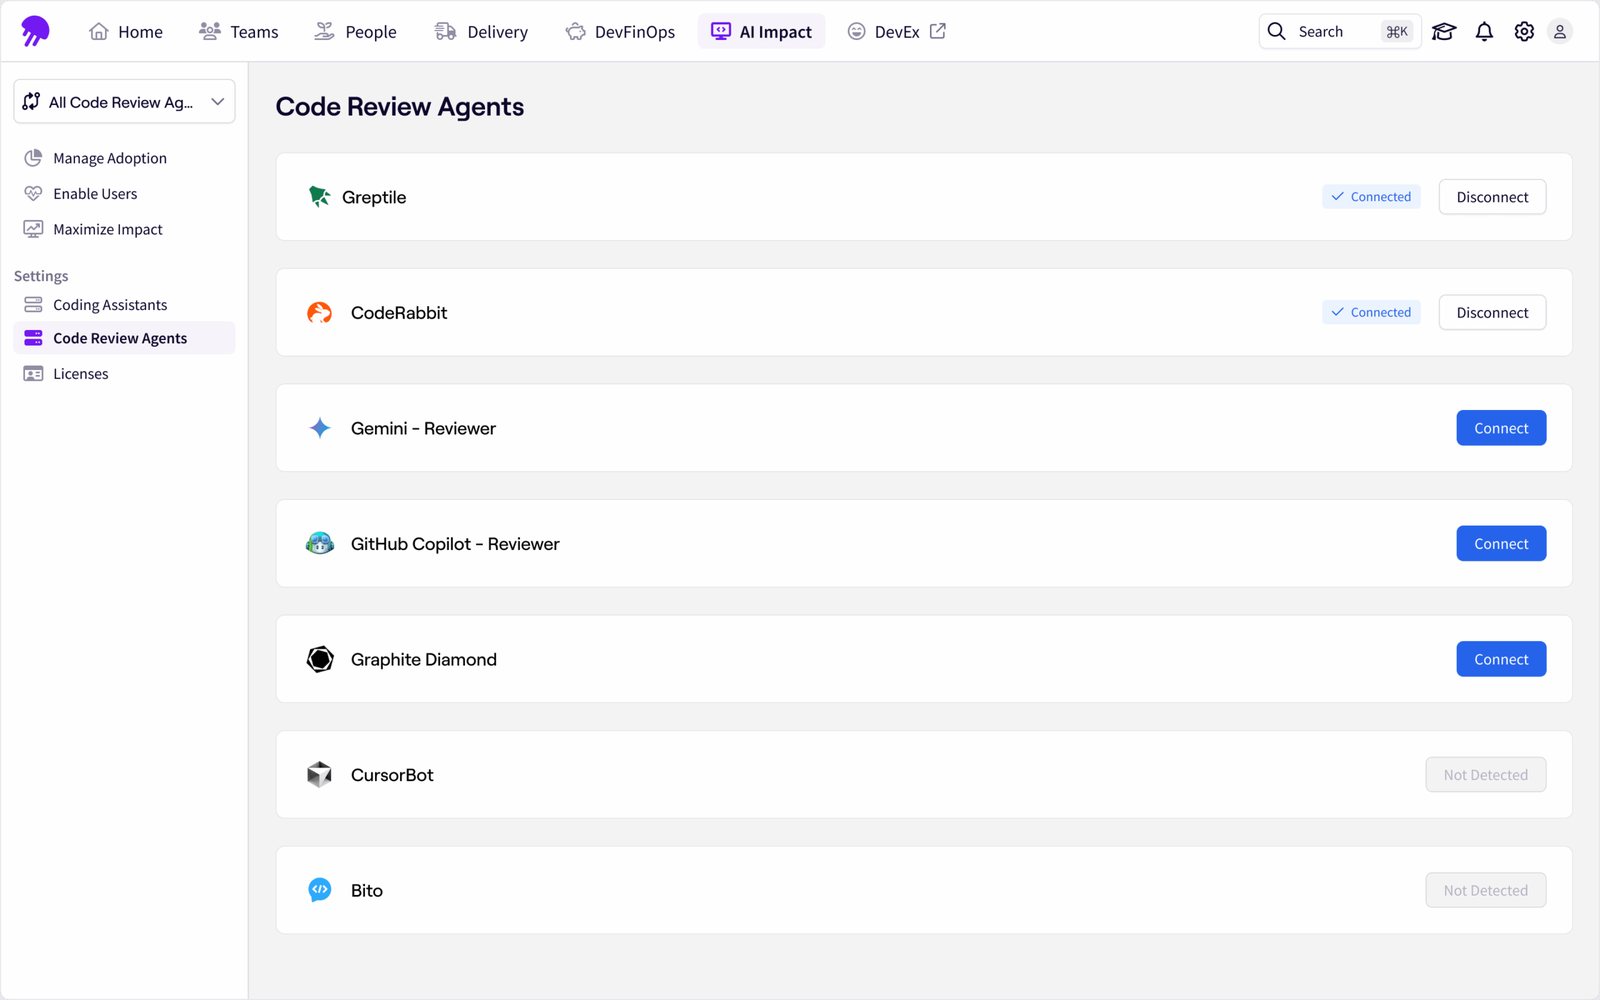
OpenAI launches CodeCritic, an automated code review agent that cuts review cycle time by 40% and starts at $20/user/month.
Groq pivots to inference-only hardware, discontinues training chips, and secures $640M in new funding.
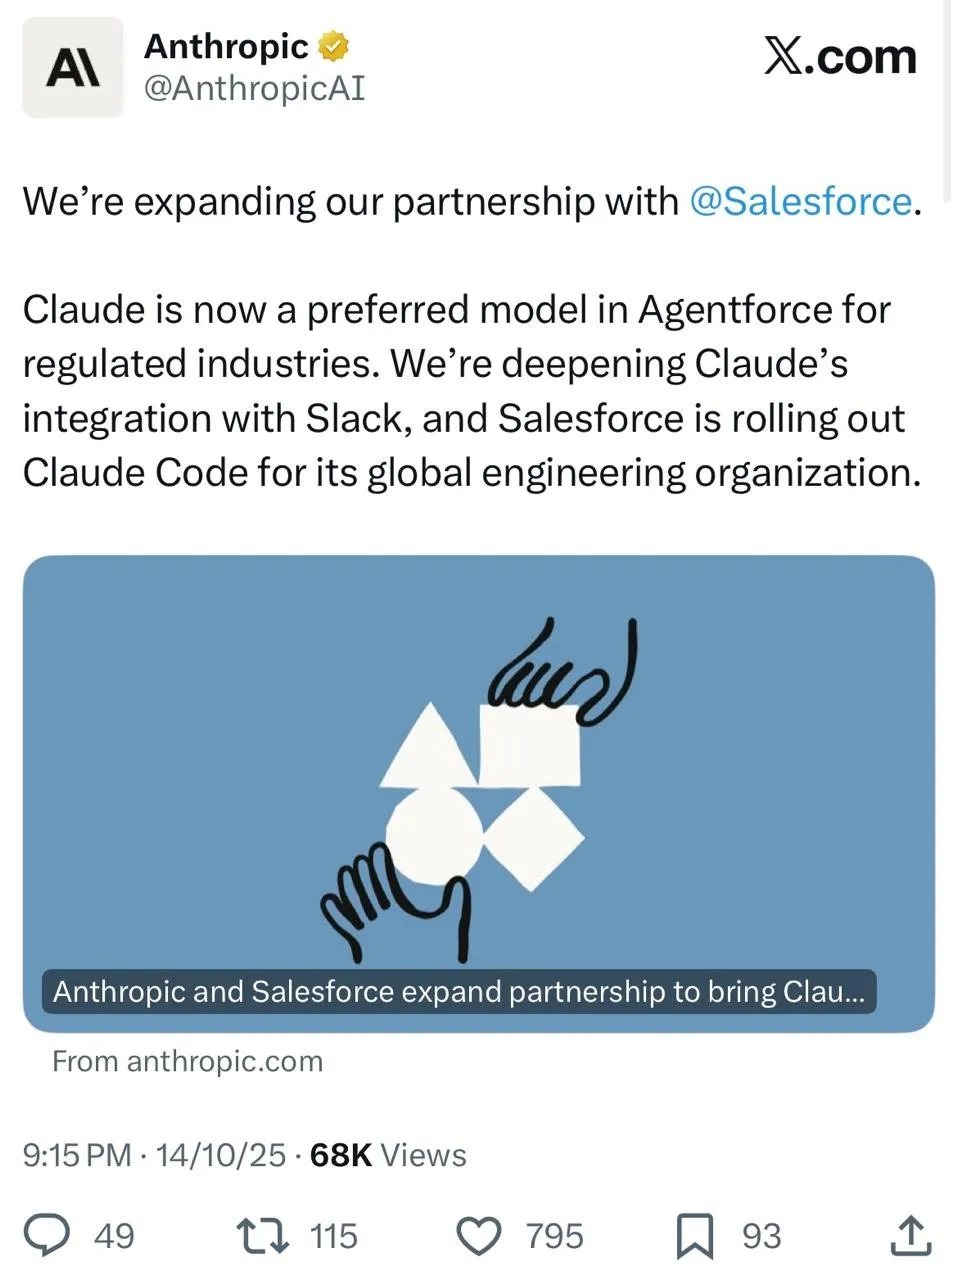
Anthropic signs a $3.5B enterprise deal with Salesforce for Claude 4 Opus across CRM workflows.
Perplexity launches Deep Research mode for enterprise, generating 50-page reports in up to 10 minutes.
Meldung 1
Mistral-Reason-7B: open-source reasoning model beats Llama-3-8B
Mistral released a 7B parameter reasoning model using chain-of-thought distillation from larger models. It achieves state-of-the-art results on math and coding benchmarks, runs on consumer GPUs with 8GB VRAM, and is available under Apache 2.0.
Florians EinordnungThis is the kind of open-source release that actually matters—small enough to run locally, strong enough to be useful.
Für deinen Alltag Download Mistral-Reason-7B today and test it on your math or coding tasks—it runs on consumer hardware and outperforms larger open models.
Ganzen Artikel lesen
Mistral dropped Mistral-Reason-7B today, and it's a big deal for anyone who needs reasoning capabilities without renting a cluster. The model uses a novel chain-of-thought distillation technique, essentially compressing the reasoning patterns of much larger models into a compact 7B parameter package. On GSM8K, it beats Llama-3-8B by 12%, and early benchmarks show similar gains on coding benchmarks like HumanEval. The weights are on Hugging Face under Apache 2.0, meaning you can fine-tune, distribute, and even commercialize it without restrictions. For developers and researchers, this is a practical tool: it fits in 8GB VRAM, so a mid-range consumer GPU can run it. The implications are clear—open-source reasoning models are catching up to proprietary ones for many tasks. If you're building a coding assistant or math tutor, this is your new baseline. Start by downloading the model and testing it on your specific use case; the chain-of-thought outputs are surprisingly interpretable.
Meldung 2
OpenAI CodeCritic: automated code review that cuts cycle time 40%
OpenAI launched CodeCritic, an automated code review agent that integrates with GitHub and GitLab. It provides line-level feedback on security, performance, and style, and early testers report 40% faster review cycles. Pricing starts at $20 per user per month.
Florians EinordnungCode review is the bottleneck in every team I know. If this actually works, it's worth the $20 just to unblock your pipeline.
Für deinen Alltag Integrate CodeCritic into your GitHub or GitLab workflow to cut review time by 40%—start with a non-critical repo to tune settings.
Ganzen Artikel lesen
OpenAI's CodeCritic is more than a linter—it's a full-fledged code review agent that understands context. It uses a fine-tuned model trained on millions of real pull requests to detect security vulnerabilities, performance bottlenecks, and style inconsistencies. The integration is seamless: it comments directly on PRs in GitHub and GitLab, and you can configure its strictness per repository. Early testers report a 40% reduction in review cycle time, which translates to faster deployments and fewer context switches for senior engineers. The pricing is aggressive at $20/user/month, making it accessible for startups and enterprises alike. For teams that struggle with review backlogs, this is a no-brainer. But remember: it's a tool, not a replacement. Use it to catch the obvious stuff so humans can focus on architecture and design. Start by enabling it on a non-critical repo, tune the feedback level, then roll out broadly.
Meldung 3
Groq pivots to inference-only, raises $640M
Groq announced it will discontinue its training chip line and focus exclusively on inference with its LPU architecture. CEO Jonathan Ross cited insufficient demand for training hardware. The company secured $640M in new funding from existing investors.
Florians EinordnungGroq's LPU was always a beast at inference speed. Smart move to double down where they actually win.
Für deinen Alltag If you need ultra-low-latency inference for real-time apps, evaluate Groq's LPU-based API—it's now their sole focus.
Ganzen Artikel lesen
Groq's pivot is a strategic retreat from a market dominated by Nvidia. The company's LPU architecture was known for low-latency inference, but training chips require massive ecosystems that Groq couldn't build. CEO Jonathan Ross was blunt: 'Insufficient market demand for training hardware.' The $640M in new funding suggests investors believe in the inference-only bet. For developers, this means Groq will likely double down on API accessibility and latency optimization. If you're building real-time applications like voice assistants or live translation, Groq's hardware could be a differentiator. The pivot also signals a broader industry trend: inference is where the money is, especially as models get smaller and run on edge devices. Keep an eye on their developer tools and pricing; they'll need to compete with Nvidia's TensorRT and cloud inference services.
Meldung 4
Anthropic signs $3.5B deal with Salesforce for Claude 4
Anthropic and Salesforce signed a $3.5B multi-year agreement granting Salesforce access to Claude 4 Opus for its Einstein AI platform. The deal includes exclusive fine-tunings for CRM workflows across Sales, Service, and Marketing Cloud.
Florians EinordnungSalesforce is betting big on Claude as the brain behind their CRM empire. This is the kind of deal that makes Anthropic a real enterprise player.
Für deinen Alltag If you use Salesforce, prepare for Claude 4 Opus integration—start testing its CRM-specific features in sandbox environments.
Ganzen Artikel lesen
This $3.5B deal is a landmark for Anthropic, positioning Claude 4 Opus as the default AI for one of the largest enterprise software platforms. Salesforce will integrate Claude into Sales Cloud, Service Cloud, and Marketing Cloud, with exclusive fine-tunings tailored to CRM workflows—things like lead scoring, customer sentiment analysis, and automated follow-ups. For Salesforce users, this means smarter automation and better insights directly within their existing tools. For the AI industry, it's a signal that enterprise buyers are willing to pay premium prices for model exclusivity. The deal also puts pressure on OpenAI and Google, who have similar partnerships with other platforms. If you're a Salesforce admin or developer, start exploring how Claude's integration will change your workflows—expect announcements at Dreamforce. For everyone else, watch how this shapes enterprise AI pricing and exclusivity trends.
Meldung 5
Perplexity Deep Research: 50-page reports in 10 minutes
Perplexity launched Deep Research mode for enterprise subscribers, generating comprehensive 50-page reports by querying multiple sources and synthesizing findings. It uses a multi-step reasoning pipeline that takes up to 10 minutes per report.
Florians EinordnungIf you're a knowledge worker drowning in research, this is a godsend. But verify the sources—automated synthesis can hallucinate.
Für deinen Alltag Use Perplexity Deep Research for initial drafts of complex reports, but always verify citations before finalizing.
Ganzen Artikel lesen
Perplexity's Deep Research mode is a significant upgrade for anyone who needs to produce thorough reports quickly. It works by automatically querying multiple sources, cross-referencing findings, and generating a structured report with citations. The multi-step reasoning pipeline can take up to 10 minutes, but the result is a 50-page document that would otherwise take hours or days. Early tests show an 80% reduction in research time for knowledge workers. The key is to treat it as a first draft—verify the sources and add your own analysis. For consultants, analysts, and students, this could be a game-changer. Perplexity is positioning it as an enterprise feature, so expect premium pricing. If you have access, start with a topic you know well to gauge accuracy, then use it for unfamiliar subjects. The citation feature is critical—always check the originals.
Prompt des Tages
Code Review Agent
Act as a senior code reviewer. Review the provided pull request for security vulnerabilities, performance bottlenecks, and style inconsistencies. Provide line-level feedback in a concise, actionable format.
Use this when you need a fast, automated code review that catches issues before merging.
Deep Dive
How to Use Chain-of-Thought Distillation for Smaller Models
Chain-of-thought (CoT) distillation is the technique behind Mistral-Reason-7B's success, and you can apply it to your own models. The idea is simple: instead of training a small model directly on raw data, you first generate reasoning traces from a larger, more capable model, then use those traces as training data. This compresses the reasoning ability of the big model into a smaller, faster, and cheaper one. The key steps are: (1) collect a dataset of problems, (2) prompt a large model (like GPT-4 or Claude) to generate step-by-step reasoning and the final answer, (3) filter out incorrect or low-quality traces, and (4) fine-tune a smaller model on the filtered dataset. The result is a model that 'thinks' like the larger model but runs in a fraction of the compute. For practical implementation, use Hugging Face's Transformers library with a causal language model like Llama-3-8B or Mistral-7B as your student. Set your learning rate low (1e-5) and train for 2-3 epochs on the CoT dataset. Monitor for overfitting by evaluating on a held-out set. The biggest mistake is using unfiltered traces—garbage in, garbage out. Always validate the reasoning quality before training. For a concrete example, take a math problem like 'A train leaves station A at 60 mph...' and have your large model output 'Step 1: Calculate distance... Step 2: Time = distance/speed... Final answer: 2 hours.' Then fine-tune your small model to produce similar step-by-step outputs. This technique is especially powerful for domain-specific tasks like code generation or medical diagnosis. Start with a small dataset of 10,000 examples, scale up as you validate.
Stop waiting for the perfect model—the one you need is already open-source and fits on your laptop.
Für Ihren Betrieb
Welcher Ablauf lohnt sich bei Ihnen zuerst?
Mit dem kostenlosen KI-Prozess-Check sehen Sie in 15 Minuten, wo in Ihrem Betrieb die meiste Zeit liegen bleibt. Oder wir sehen es uns in 30 Minuten gemeinsam an, kostenlos und ohne Verkaufsgespräch.